Best LLM Evaluation and Observability Tools in 2026: The Complete Guide
An in-depth 2026 guide to the best LLM evaluation and observability tools - what they do, how evaluation and observability differ, the metrics that matter, how to choose, and a detailed comparison of the…

Shipping a large language model (LLM) application is deceptively easy; knowing whether it actually works - and keeping it working in production - is the hard part. Unlike traditional software, an LLM app is non-deterministic: the same prompt can return different answers, there is rarely a single correct output, and failures are quiet. A model does not throw an exception when it hallucinates a fact, drifts off-topic, leaks sensitive data, or quietly gets more expensive. The only way to build reliable LLM products is to measure them rigorously and watch them continuously - which is exactly what LLM evaluation and observability tools exist to do.
In 2026 this has become its own discipline, often called LLMOps, with a fast-growing ecosystem of platforms for tracing, evaluating, and monitoring AI applications and agents. This guide explains what these tools do, how evaluation differs from observability, the metrics that actually matter, how to choose a platform, and a detailed comparison of the leading options - open source and commercial. If you are building production AI and want a team that treats evaluation as a first-class concern, VOCSO's AI development services can help you design, measure, and operate it properly.
Evaluation vs observability: what is the difference?
The two terms are often used together, and the best tools do both, but they answer different questions. Evaluation asks: is the output good? It scores quality - accuracy, relevance, faithfulness, safety - against datasets, references, or judges, usually during development and in CI. Observability asks: what is actually happening? It traces every step of a request in production - prompts, retrievals, tool calls, tokens, latency, and cost - so you can debug failures and monitor behavior over time. Evaluation tells you whether your app is correct; observability tells you what it did and why.
Why LLM apps are so hard to evaluate
If you come from traditional software testing, LLMs break your assumptions. There are a handful of reasons these tools exist at all:
- Non-determinism. The same input can produce different outputs, so a single pass/fail assertion is not enough - you need statistical, repeated measurement.
- No single ground truth. Many tasks (summaries, chat, generation) have many acceptable answers, so you cannot just compare against one expected string.
- Silent failures. Hallucinations, subtle irrelevance, and tone problems do not raise errors; they just quietly erode trust.
- Multi-step complexity. Agents and RAG pipelines chain retrieval, tool calls, and multiple model calls - a wrong answer could originate anywhere, so you need to trace the whole chain.
- Drift and cost. Model providers update models, your data changes, and token spend creeps up - all of which need continuous monitoring, not a one-time test.
Together these make LLM quality an ongoing operating discipline rather than a checkbox at launch. We dug into the failure side of this in debugging NLP failures in production, and into agent-specific evaluation in how to evaluate AI agents.
Why evaluation and observability pay off
Investing in this discipline is not overhead - it is what lets you ship AI confidently and keep it good. The payoff shows up in several concrete ways:
- Reliability and trust. You catch hallucinations, regressions, and safety issues before your users do, protecting the credibility of the product and the brand behind it.
- Faster, data-driven iteration. With evals, improving a prompt or swapping a model is a measured experiment, not a guess - you can prove a change is better before it ships, and roll it back if it is not.
- Cost control. Per-step token and cost tracking exposes the expensive calls, letting you cache, trim prompts, or route simpler requests to cheaper models without hurting quality.
- Confident, faster releases. When evals gate your pipeline, you can ship more often because a safety net catches quality regressions automatically.
- Risk and compliance. Traces and scores give you an audit trail and continuous safety monitoring - increasingly important as AI regulation tightens and as AI handles higher-stakes tasks.
- Competitive quality. In a market where everyone has access to the same base models, the teams that measure and tune relentlessly ship noticeably better experiences.
In short, evaluation and observability convert AI from a hopeful experiment into an engineering practice - which is the difference between a demo and a dependable product.
The LLM evaluation and observability lifecycle
Good teams treat this as a loop, not a phase. You develop against evaluation datasets, trace what happens, score the results, monitor production, and feed real failures back into your datasets - tightening quality on every turn.
Types of LLM evaluation
Not all evaluation is the same, and good tools support several methods because each catches different problems. The main approaches you will combine are:
The workhorse of modern evaluation is LLM-as-judge: using a capable model to grade outputs against a rubric. It scales far better than human review and is the engine behind most automated eval suites - but it has to be calibrated against human judgment, or you end up trusting a grader that is itself biased or wrong. For RAG specifically, reference-free metrics like faithfulness (is the answer grounded in the retrieved context?) and context relevance matter most, because you rarely have a single gold answer.
The metrics that matter
A good platform measures across four dimensions. Tracking only one - usually cost or latency, because they are easy - is how quality problems slip through.
- Quality: correctness, relevance, coherence, and faithfulness (no hallucination beyond the source).
- RAG-specific: context precision and recall - did retrieval fetch the right information, and did the answer use it?
- Operational: latency, token usage, and cost per request - the numbers that decide whether your app is viable at scale.
- Safety: toxicity, bias, PII leakage, and prompt-injection or jailbreak attempts.
What makes LLM observability distinct from classic APM is the trace: a step-by-step record of a single request as it moves through your prompts, retrievers, tools, and model calls. A trace is where you see exactly which step produced a bad answer - and where evaluation scores get attached so quality and behavior live in one view.
What LLM observability captures in practice
Beyond the headline trace, a mature observability platform records a structured picture of every interaction so you can slice, debug, and monitor it later. The building blocks you will work with are:
- Traces and spans. A trace is one end-to-end request; spans are its nested steps (retrieval, a model call, a tool call), each with its own timing, inputs, and outputs - so you can zoom into exactly where things went wrong.
- Sessions and threads. Related traces grouped into a conversation or user journey, which matters for chat and agents where context spans many turns.
- Metadata and tags. User or tenant IDs, model name and version, prompt version, environment, and custom tags - the dimensions you filter and compare by when quality shifts.
- Token and cost accounting. Per-step token counts and spend, so you can find the expensive call in a chain and control cost before it surprises you.
- User feedback. Thumbs up/down, corrections, and implicit signals attached to the trace that produced them - a direct line to what real users think.
- Scores and alerts. Evaluation results attached to traces, plus alerting when a metric crosses a threshold so regressions page you instead of hiding in a dashboard.
This is what separates LLM observability from a simple log file: everything about a request - what it did, what it cost, how good it was, and what the user thought - lives in one place you can query. When a production issue surfaces, that is the difference between a five-minute fix and a day of guesswork, as we described in debugging NLP failures in production.
Core evaluation metrics, defined
The metric names get thrown around loosely, so it helps to pin down what each actually measures. These are the ones you will configure most often:
- Faithfulness (groundedness): does the answer stay true to the retrieved context, without inventing facts? The primary defense against hallucination in RAG.
- Answer relevance: does the response actually address the user's question, rather than drifting to something adjacent?
- Context precision: of the chunks retrieval returned, how many were actually relevant? Low precision means your retriever is adding noise.
- Context recall: did retrieval fetch all the information needed to answer? Low recall means the model is missing facts it should have had.
- Correctness: for tasks with a known answer, is the output factually right compared to the reference?
- Toxicity and safety: is the output free of harmful, biased, or policy-violating content, and does it resist jailbreaks?
- Coherence and fluency: is the answer well-structured and readable - the baseline table stakes of a good response?
For RAG systems, faithfulness plus context precision and recall together tell you whether a bad answer is a retrieval problem or a generation problem - a distinction that changes how you fix it.
LLM observability vs traditional monitoring
It is fair to ask why you cannot just use the application performance monitoring (APM) you already have. Traditional APM watches the infrastructure around your app - CPU, memory, request rates, error codes, and latency - and treats the response itself as an opaque payload. That tells you the service is up and fast, but nothing about whether the answer it returned was correct, grounded, safe, or relevant. For an LLM app, a request can return a clean HTTP 200 in 400 milliseconds and still contain a confidently wrong, made-up answer - the kind of failure classic APM is blind to by design.
LLM observability fills that gap by understanding the semantic content of each request: the prompt, the retrieved context, the tool calls, the tokens, and - via attached evaluations - the quality of the output. The two are complementary rather than competing. You still want APM for infrastructure health, and LLM observability for AI quality; mature teams run both. Some APM vendors are now adding LLM features (Datadog's LLM Observability is one example), but purpose-built tools generally go deeper on the things that matter for AI - evaluation datasets, LLM-as-judge scoring, prompt versioning, and RAG-specific metrics.
How to choose an LLM evaluation and observability tool
The ecosystem is crowded, and tools overlap. Weigh these factors against how you build, because migrating later means re-instrumenting your whole app:
A few of these deserve emphasis. OpenTelemetry (OTel) support matters more every year, because it lets you instrument once and avoid lock-in. Self-hosting is decisive for teams with strict data rules - sending every prompt and completion to a third-party SaaS is a non-starter in some industries. And whether evaluation is first-class or an afterthought separates tools that merely log from tools that actually help you improve quality. For a vendor-vetting framework, our guide on evaluating AI agents applies directly.
The best LLM evaluation and observability tools in 2026
There is no single winner - the right tool depends on your stack, whether you need self-hosting, and whether your priority is tracing, evaluation, or both. The market splits into observability-first platforms, evaluation-first frameworks, all-in-one suites, gateways, and enterprise offerings. Here are the leaders, with what each is best for. (Pricing and ownership shift constantly and vary across sources, so treat figures as directional and confirm on each vendor's site.)
1. Langfuse - best open-source all-rounder
Langfuse has become the default open-source choice for teams that want serious LLM observability without handing their data to a vendor. It unifies tracing, evaluations, prompt management, and datasets in one MIT-licensed platform you can run entirely inside your own infrastructure. Engineers instrument the app with an SDK, inspect full traces of every request, score outputs with built-in or custom evaluators, and version prompts from the same UI. A generous free Hobby tier and an active community make it easy to adopt, and the self-host option is decisive in regulated settings where prompts and completions cannot leave the network.
Best for: most teams that want tracing plus evaluations with the freedom to self-host.
Watch for: running your own deployment adds real operational overhead compared with pure SaaS.
Pros:
- Open source and fully self-hostable (MIT)
- Tracing, evaluations, prompt management and datasets in one tool
- Large, active community and fast releases
Cons:
- Self-hosting adds operational overhead
- The deepest managed features sit in the paid cloud tiers
2. LangSmith - best for LangChain and LangGraph stacks
LangSmith is the observability and evaluation platform built by the team behind LangChain, and its biggest advantage is how deeply it understands LangChain and LangGraph applications. On that stack instrumentation is almost automatic, and every chain, agent step, and tool call appears in a detailed trace you can replay and debug. Beyond tracing it offers dataset management, offline and online evaluations, prompt playgrounds, and annotation queues for human review. It is a polished, mature commercial product that scales from a solo developer on the free tier to a large team on usage-based plans.
Best for: teams building on LangChain or LangGraph who want first-class, native observability.
Watch for: it is a commercial SaaS with usage-based pricing, and it shines most within the LangChain ecosystem.
Pros:
- Native, deep LangChain and LangGraph tracing
- Strong debugging, datasets and evaluations
- Polished, mature UI
Cons:
- Commercial SaaS with usage-based pricing
- Most valuable inside the LangChain ecosystem
3. Arize Phoenix - best open-source, OpenTelemetry-native option
Arize Phoenix is an open-source observability and evaluation library built on OpenTelemetry, which makes it a natural fit for teams that want vendor-neutral, standards-based instrumentation. You can run it locally in a notebook while developing or self-host it in production, and it excels at tracing complex LLM and RAG pipelines, visualizing embeddings, and running structured evaluations. It is backed by Arize, whose enterprise platform, Arize AX, extends the same ideas to large-scale production monitoring with drift detection and alerting, so many teams prototype on Phoenix and graduate to AX for managed scale.
Best for: teams that want an OpenTelemetry-standard, open-source tool with strong RAG evaluation.
Watch for: there is a feature and scale gap between open-source Phoenix and the commercial Arize AX.
Pros:
- Open source and OpenTelemetry-native
- Strong tracing and RAG evaluation
- Runs locally or self-hosted
Cons:
- Feature gap between OSS Phoenix and enterprise Arize AX
- Scale needs the paid Arize AX product
4. Braintrust - best for evaluation-driven CI/CD
Braintrust approaches the problem from the evaluation side first, built to make evals as rigorous and repeatable as unit tests. It offers first-class experiment tracking, dataset versioning, and side-by-side comparison of prompt and model changes, and teams wire it into CI so a pull request that degrades quality fails the build - turning the question of whether a change helped from a guess into a measured answer. It also records production logs and supports LLM-as-judge scoring, but its center of gravity is systematic evaluation and fast iteration rather than deep distributed tracing.
Best for: teams that treat evaluations like tests and want them gating every release.
Watch for: if continuous production tracing is your main need, a tracing-first tool may fit better.
Pros:
- Evaluation-first with excellent experiment tracking
- Gates releases on eval results in CI
- Fast prompt iteration
Cons:
- Lighter on pure production tracing
- Commercial SaaS
5. Weights & Biases Weave - best for ML teams already on W&B
Weave extends the well-known Weights & Biases platform to LLM applications, bringing tracing, evaluation, and experiment tracking to teams that already manage their machine-learning work there. Its strength is continuity: the same place you track training runs and model versions now captures LLM traces, logs evaluation results, and compares prompt experiments, with the lineage and collaboration features W&B users expect. For an ML-mature organization, that single view across classical ML and generative AI is a real advantage and avoids introducing yet another separate tool.
Best for: organizations already standardized on Weights & Biases.
Watch for: the value is highest when you are already invested in the W&B ecosystem.
Pros:
- Tracing and evaluation integrated with Weights & Biases
- A natural fit for existing W&B users
- Strong experiment lineage
Cons:
- Most value only if you already use W&B
6. Helicone - best lightweight gateway for logging and cost
Helicone takes a refreshingly lightweight approach: route your model calls through its gateway - often a one-line base-URL change - and you immediately get logging, cost tracking, caching, rate limiting, and analytics with almost no code. It is open source and self-hostable, which appeals to teams that want quick visibility and spend control without a heavy integration, and because it sits in the request path it is a natural place to add caching and key management. Its evaluation features are lighter than dedicated frameworks, so many teams pair it with one.
Best for: teams that want fast, low-effort logging and cost visibility.
Watch for: a proxy sits in your request path, and deep evaluation is lighter than in eval-first tools.
Pros:
- One-line gateway integration
- Instant logging, cost tracking and caching
- Open source and self-hostable
Cons:
- A proxy sits in your request path
- Evaluation is lighter than eval-first tools
7. DeepEval (Confident AI) - best open-source eval framework
DeepEval, from Confident AI, brings a developer-native, pytest-style experience to LLM evaluation: you write test cases, assert on metrics, and run them locally or in CI exactly like unit tests. It ships a large library of ready-made metrics - faithfulness, answer relevancy, hallucination, bias, toxicity, and RAG-specific scores - and supports custom metrics and LLM-as-judge grading. As an Apache-2.0 library it slots into existing Python workflows with no platform lock-in, and for teams that want dashboards and monitoring on top, Confident AI provides a hosted platform built on the same metrics.
Best for: engineers who want to write and run LLM evals like unit tests.
Watch for: you assemble the observability side yourself unless you adopt the paid Confident AI platform.
Pros:
- Pytest-style evals engineers love
- A large library of ready-made metrics
- Open source (Apache-2.0)
Cons:
- You add the observability layer separately unless you adopt Confident AI
8. TruLens - best for RAG evaluation research
TruLens is an open-source evaluation library best known for its feedback functions and the RAG triad - groundedness, context relevance, and answer relevance - which together reveal whether a weak RAG answer comes from retrieval or generation. Developed in the open under an MIT license, it instruments your chains, records inputs and outputs, and scores them against programmable feedback functions you can tune. It is especially popular with teams doing serious work on RAG architectures who want fine-grained, explainable quality signals rather than a single opaque score.
Best for: teams iterating heavily on RAG pipelines who want granular quality feedback.
Watch for: it is a library focused on evaluation, not a full production monitoring suite.
Pros:
- Open source (MIT)
- RAG-triad feedback functions
- Great for RAG research and iteration
Cons:
- A library, not a full production monitoring suite
- You pair it with a tracing tool
9. Opik (Comet) - best budget-friendly open-source platform
Opik, from Comet, is a newer open-source (Apache-2.0) platform that combines tracing and evaluation with one of the more affordable hosted tiers in the space. It captures detailed traces of LLM and agent calls, supports online and offline evaluation with LLM-as-judge and heuristic metrics, and offers dashboards for monitoring quality and cost. Backed by Comet's experiment-tracking heritage, it is a strong value option for teams that want open-source flexibility and the ability to self-host without the price tag of the enterprise incumbents.
Best for: cost-conscious teams wanting open-source tracing plus evaluations.
Watch for: it is younger than some rivals, so confirm your specific integrations are supported.
Pros:
- Open source (Apache-2.0)
- An affordable hosted tier
- Tracing plus evaluations, backed by Comet
Cons:
- Younger than some rivals
- Confirm your specific integrations are covered
10. Galileo - best for enterprise evaluation and guardrails
Galileo is a commercial platform aimed at enterprises that need rigorous LLM evaluation, production observability, and real-time guardrails in one place. It focuses on measuring quality at scale, detecting hallucinations and failures, and blocking bad or unsafe outputs before they reach users - capabilities that matter most for regulated, high-stakes deployments. Now part of Cisco, it is positioned as an enterprise-grade system with the support, scale, and governance large organizations expect, rather than a lightweight tool you self-host over a weekend.
Best for: enterprises wanting a managed evaluation-plus-observability platform with guardrails.
Watch for: it is a commercial, enterprise-oriented product rather than a lightweight self-host option.
Pros:
- Enterprise-grade evaluation, guardrails and monitoring
- Real-time output protection
- Managed scale
Cons:
- Commercial and enterprise-oriented
- Overkill for small projects
11. Humanloop & LangWatch - best for prompt management and collaboration
These two tools serve collaborative, quality-focused teams from slightly different angles. Humanloop centers on prompt management, evaluation, and human-feedback workflows, giving product managers, engineers, and domain experts a shared place to iterate on prompts and systematically collect human ratings. LangWatch combines observability with evaluation and quality monitoring, often with an OpenTelemetry-friendly, gateway-style setup that is quick to adopt. Both suit cross-functional teams where non-engineers are deeply involved in shaping and judging LLM behavior, and where prompt iteration is a team effort rather than a solo engineering task.
Best for: cross-functional teams collaborating on prompts, evaluation, and human feedback.
Watch for: confirm each tool's depth on the specific capability you most need before committing.
Pros:
- Strong prompt management and human-feedback workflows (Humanloop)
- OTel-friendly observability and quality monitoring (LangWatch)
- Good for cross-functional teams
Cons:
- Confirm each tool depth on the capability you need most
- Both are commercial
12. Custom / OpenTelemetry-based stack - best for full control
Rather than adopting a single platform, some teams instrument their own observability using OpenTelemetry plus a trace backend, combined with an open evaluation library such as DeepEval or TruLens. This maximizes control, avoids vendor lock-in, and keeps every prompt and completion inside your own environment - which can be essential under strict data-residency or compliance rules. The trade-off is that you own the plumbing: building the pipelines, dashboards, and alerting, and maintaining them as your needs evolve. It is the right path for teams with specific requirements and the engineering capacity to support it.
Best for: teams with strict requirements and the engineering capacity to own their stack.
Watch for: it is real engineering - which is where a partner like VOCSO's MLOps engineers can help.
Pros:
- Maximum control and no vendor lock-in
- Instrument once with OpenTelemetry
- Fits strict data-residency rules
Cons:
- You build and maintain the plumbing yourself
- Real, ongoing engineering effort
13. PromptLayer - best for prompt management and non-engineer collaboration
PromptLayer puts prompt management at the center: it versions, logs, and organizes your prompts, tracks every request and response, and wraps evaluation and analytics around them in a UI that non-engineers can use comfortably. That makes it a strong fit for teams where product managers or content specialists own and iterate on prompts and want to see exactly how each version performs in production. It integrates with common LLM providers and frameworks and acts as a shared system of record for prompt history and experimentation across a team.
Best for: teams where non-engineers own prompts and want to iterate on and track them.
Watch for: deep production tracing is lighter than in dedicated observability-first platforms.
Pros:
- Prompt versioning and logging
- A UI friendly to non-engineers
- Good team collaboration
Cons:
- Production tracing is lighter than observability-first platforms
14. Langtrace - best for open-source, OpenTelemetry-native tracing
Langtrace is an open-source tracing tool built on OpenTelemetry, designed to capture detailed, standards-compliant traces of LLM, vector-database, and framework calls in a way you fully control. Because it emits OTel data, you can export traces to whatever backend you already run and avoid being locked into a proprietary format - a meaningful advantage for teams that value portability and already operate observability infrastructure. It focuses squarely on high-quality tracing and instrumentation, so teams that also need rich evaluation typically pair it with a dedicated eval library.
Best for: teams that want standards-based, open, portable tracing they fully control.
Watch for: it focuses on tracing, so you may want to pair it with a dedicated evaluation library.
Pros:
- Open source and OpenTelemetry-native
- Vendor-neutral traces you can export anywhere
- Standards-based
Cons:
- Focused on tracing, so pair it with a dedicated eval library
15. Datadog LLM Observability - best for teams already on Datadog
For organizations that already run Datadog for infrastructure and application monitoring, its LLM Observability product brings prompt-and-response tracing, quality and safety checks, and token-and-cost tracking into the same platform, dashboards, and alerting your operations team already uses. That consolidation is the main draw: instead of adding a separate AI-specific vendor, your LLM telemetry lives alongside the rest of your stack, with Datadog's enterprise-grade reliability, access controls, and support. It is a pragmatic choice when operational consolidation matters more than best-of-breed, AI-native evaluation depth.
Best for: enterprises consolidating AI monitoring into an existing Datadog deployment.
Watch for: it is part of a broader commercial platform, so it fits best when you are already invested in it.
Pros:
- LLM tracing, quality checks and cost inside your existing Datadog stack
- One platform for ops and AI
- Enterprise support
Cons:
- Part of a broader commercial platform
- Best only if already on Datadog
16. Fiddler AI - best for enterprise model monitoring and safety
Fiddler brings enterprise-grade AI observability with a long heritage in classical ML model monitoring, now extended to LLMs. Alongside tracing, it emphasizes the concerns large, regulated organizations care about: drift detection, safety and bias monitoring, explainability, and governance across the model lifecycle. That makes it less of a developer convenience tool and more of a platform for risk, compliance, and ML-ops teams that need defensible oversight of production AI. For enterprises that must prove how and why their models behave, that governance depth is the differentiator.
Best for: regulated enterprises that need monitoring, explainability, and governance in one place.
Watch for: it is an enterprise platform, heavier than a lightweight self-host tool.
Pros:
- Enterprise monitoring with drift, safety and governance
- Mature ML-monitoring heritage
- Explainability built in
Cons:
- Heavy and enterprise-only
- More than a lightweight self-host setup needs
Quick comparison
| Tool | Best for | Type | Open source? |
|---|---|---|---|
| Langfuse | Open-source all-rounder | Observability + evals | Yes (MIT) |
| LangSmith | LangChain / LangGraph stacks | Observability + evals | No (SaaS) |
| Arize Phoenix | OTel-native open source | Observability + evals | Yes |
| Braintrust | Eval-driven CI/CD | Evaluation-first | No (SaaS) |
| W&B Weave | Teams on Weights & Biases | All-in-one | Partly |
| Helicone | Logging & cost via gateway | Gateway / proxy | Yes |
| DeepEval | Evals as unit tests | Eval framework | Yes (Apache-2.0) |
| TruLens | RAG evaluation | Eval framework | Yes (MIT) |
| Opik | Budget open-source platform | Observability + evals | Yes (Apache-2.0) |
| Galileo | Enterprise evals + guardrails | Enterprise | No |
Pros, cons, and pricing at a glance
To make the shortlist easier, here is a condensed view of each major tool's strengths, weaknesses, and pricing. Pricing is directional - it changes often and depends heavily on usage - so confirm the current numbers on each vendor's pricing page before you commit.
| Tool | Pros | Cons | Pricing (directional) |
|---|---|---|---|
| Langfuse | Open source & self-hostable; tracing, evals & prompt management in one; strong community | Self-hosting adds ops overhead | Free (MIT, self-host); cloud free tier, paid Pro/Team |
| LangSmith | Deep LangChain/LangGraph integration; strong debugging & evals | Commercial SaaS; best inside the LangChain stack | Free developer tier; usage-based (per seat + per trace); Enterprise |
| Arize Phoenix | Open source, OpenTelemetry-native; strong RAG evaluation | Feature gap between OSS Phoenix and Arize AX | Free (open source); Arize AX enterprise (custom) |
| Braintrust | Evaluation-first; great experiments & CI gating | Lighter on pure production tracing | Free tier; paid Pro; Enterprise |
| W&B Weave | Fits the Weights & Biases ecosystem; tracing + evals | Most value only if already on W&B | Free tier; paid (W&B plans); Enterprise |
| Helicone | One-line gateway logging; cost tracking & caching | Proxy sits in the request path; lighter evals | Free (OSS/self-host); free cloud tier, paid from ~$20/mo |
| DeepEval | Pytest-style evals; rich metric library; open source | Observability is separate unless you add Confident AI | Free (Apache-2.0); Confident AI free + paid tiers |
| TruLens | Open source; RAG-triad feedback functions | A library, not a full monitoring suite | Free (MIT) |
| Opik (Comet) | Open source; affordable hosted tier; tracing + evals | Younger ecosystem; check your integrations | Free (Apache-2.0); low-cost hosted; Enterprise |
| Galileo | Enterprise evals, guardrails & monitoring | Commercial, enterprise-oriented | ~$100/mo Pro; Enterprise (custom) |
| PromptLayer | Prompt versioning + logging; friendly to non-engineers | Lighter production tracing | Free tier; paid Pro; Enterprise |
| Fiddler | Enterprise monitoring, drift & governance | Heavy; enterprise-only | Enterprise (custom) |
Open source vs commercial, self-host vs SaaS
Two decisions shape your shortlist more than any feature. The first is open source vs commercial: open tools (Langfuse, Phoenix, DeepEval, TruLens, Opik, Helicone) give you transparency, community momentum, and no per-seat lock-in, while commercial platforms (LangSmith, Braintrust, Galileo, Humanloop) often lead on polish, support, and managed scale. The second is self-host vs SaaS: SaaS is the fastest route to value, but if your prompts and completions contain sensitive or regulated data, self-hosting an open tool inside your own environment may be the only acceptable option. Many teams land on an open-source tool they can self-host now and move to managed hosting later - or vice versa - so favoring tools that offer both paths protects you. If data residency and compliance are central to your decision, our AI consulting services can help you weigh the trade-offs.
Best practices for LLM evaluation and observability
The tool is necessary but not sufficient; how you use it decides whether you actually ship reliable AI. The teams that do this well share a handful of habits:
- Build a real evaluation dataset early. Curate representative inputs with expected behaviors, and grow it continuously from production failures. Your dataset is your most valuable quality asset.
- Calibrate your LLM-as-judge. Spot-check the judge against human ratings before you trust it, and re-check periodically - an uncalibrated grader gives confident, wrong scores.
- Run evals in CI. Gate releases on eval results so a prompt or model change cannot silently regress quality. Treat evals like tests.
- Trace everything in production. Instrument the full chain - retrieval, tools, and model calls - so when something goes wrong you can see exactly where.
- Monitor the full metric set. Watch quality, cost, latency, and safety together; optimizing one in isolation usually degrades another.
- Keep humans in the loop. Sample real conversations for human review, especially for high-stakes or ambiguous outputs, and feed what you learn back into datasets and guardrails.
Build vs buy: custom instrumentation or a platform?
For most teams, adopting a platform is the right call - it is faster and the tools are mature. But when you have strict data-residency rules, unusual workflows, or a desire to avoid lock-in, instrumenting your own stack on OpenTelemetry with an open eval library is a legitimate path. The trade-off is the usual one: control and fit versus speed and maintenance. Whichever way you lean, the goal is the same - make quality measurable and visible. VOCSO builds and operates production AI systems with evaluation and observability baked in, through our AI agent development and generative AI teams, and can extend your in-house capability with dedicated AI developers.
Step-by-step: adding evaluation and observability to your LLM app
If you are starting from a bare LLM app, here is a pragmatic order of operations that gets you to reliable, measurable AI without boiling the ocean.
- Instrument tracing first. Wrap your LLM, retrieval, and tool calls so every request produces a trace. You cannot evaluate or debug what you cannot see, so visibility comes before everything else.
- Define success and a rubric. Decide what a good answer means for your use case and write it down as clear, gradable criteria - this becomes the basis for both human and LLM-as-judge scoring.
- Build a starter evaluation dataset. Collect a few dozen representative inputs with expected behaviors, drawn from real or realistic usage, and treat it as a living asset you keep growing.
- Set up an LLM-as-judge and calibrate it. Configure automated scoring against your rubric, then spot-check it against human ratings until you trust its judgments.
- Put evals in CI. Run the dataset against every prompt or model change and fail the build on regressions, so quality is enforced like any other test.
- Turn on production monitoring and alerts. Score a sample of live traffic, watch quality, cost, latency, and safety, and alert when any of them crosses a threshold.
- Close the loop. Review failed traces and user feedback weekly, add the hard cases to your dataset, and let each iteration raise the floor on quality.
Common mistakes to avoid
- Measuring only cost and latency. They are easy to track and important - but they tell you nothing about whether answers are correct.
- Trusting an uncalibrated LLM judge. A grader that has not been checked against humans can be confidently wrong at scale.
- Evaluating once, at launch. Models, data, and usage drift; evaluation and monitoring have to be continuous.
- No production tracing. Without traces, a bad answer is a mystery you cannot debug.
- Ignoring data privacy. Piping every prompt and completion to a third-party SaaS can be a compliance problem - check before you wire it up.
Where LLM evaluation and observability are heading
The frontier in 2026 is agents. As LLM apps become multi-step agents that plan, call tools, and act, evaluation has to judge whole trajectories - not just a final answer - and observability has to trace long, branching runs. Expect deeper agent-trajectory evaluation, multimodal evals (image, audio, and document inputs scored alongside text), real-time guardrails that block bad outputs before they reach users, and continued consolidation around OpenTelemetry as the common instrumentation standard. The throughline is clear: as AI systems take on more autonomy, measuring and watching them stops being optional and becomes core infrastructure.
Which should you choose?
- Want one open-source tool for tracing and evals: start with Langfuse (or Arize Phoenix for an OTel-native option).
- Building on LangChain/LangGraph: LangSmith is the native fit.
- Evaluation-driven team that gates releases on quality: Braintrust or DeepEval.
- Iterating heavily on RAG: TruLens or Arize Phoenix for fine-grained RAG metrics.
- Just need logging and cost visibility fast: Helicone.
- Enterprise scale with guardrails: Galileo, Arize AX, or Humanloop.
Frequently asked questions
What is the difference between LLM evaluation and observability? Evaluation scores whether outputs are good (accuracy, relevance, faithfulness, safety), usually in development and CI. Observability traces what actually happened in production - prompts, retrievals, tool calls, tokens, latency, and cost - so you can debug and monitor. The best tools do both, and attach eval scores to production traces.
What is LLM-as-judge, and can I trust it? It is using a capable model to grade outputs against a rubric, which scales far better than human review. You can trust it only after calibrating it against human ratings and re-checking periodically; an uncalibrated judge produces confident but unreliable scores.
Do I need a separate tool, or can I use my existing APM? Classic application monitoring tracks latency and errors but does not understand prompts, tokens, retrieval quality, or hallucination. LLM-specific tools add tracing of the model chain plus quality evaluation, which general APM lacks - though some observability stacks are adding LLM features.
Are open-source LLM observability tools good enough for production? Yes. Tools like Langfuse, Arize Phoenix, and Opik are used in production by serious teams, and self-hosting them is often preferable when data cannot leave your environment. Commercial tools mainly add polish, support, and managed scale.
How do I evaluate a RAG system specifically? Use reference-free metrics: faithfulness (is the answer grounded in retrieved context?), context precision and recall (did retrieval fetch and use the right information?), and answer relevance. Frameworks like TruLens and Arize Phoenix specialize in these RAG metrics.
How much do these tools cost? Open-source tools are free to self-host (you pay for infrastructure); hosted tiers range from free Hobby plans to roughly $80-$100+/month for pro tiers, up to custom enterprise contracts. Usage-based pricing (per trace or per seat) can grow with volume, so model your real traffic before committing.
Do these tools work with any LLM provider? Almost all are model-agnostic - they work with OpenAI, Anthropic, Google, and open-weight models alike, usually through SDK wrappers, a proxy, or OpenTelemetry instrumentation. That lets you compare models and switch providers without losing your evaluation history.
What role does OpenTelemetry play? OpenTelemetry (OTel) is becoming the common standard for instrumenting LLM apps. Tools that speak OTel let you instrument your code once and send traces to different backends, which reduces lock-in and makes it easier to change platforms later.
How do I evaluate an AI agent rather than a single call? Agents need trajectory evaluation: scoring the whole sequence of steps - did it choose the right tools, in the right order, and reach the correct outcome - not just the final text. Observability tools that trace multi-step runs, combined with agent-aware eval metrics, make this possible. Our guide on how to evaluate AI agents goes deeper.
Do I need both an evaluation framework and an observability platform? Not necessarily two separate products - many platforms (Langfuse, LangSmith, Phoenix, Braintrust) do both. But the two jobs are distinct, so if you adopt an eval-only framework like DeepEval or TruLens, pair it with a tracing tool to cover production monitoring.
Can I evaluate LLM outputs without having correct answers to compare against? Yes - that is what reference-free evaluation is for. LLM-as-judge grading against a rubric, and metrics like faithfulness and answer relevance, score quality without a gold answer, which is essential for open-ended tasks and RAG where a single correct response does not exist.
How often should I run evaluations? Run your dataset in CI on every prompt, model, or retrieval change so regressions are caught before release, and continuously score a sample of production traffic so you catch issues that only appear with real users and real data drift. Evaluation is a standing process, not a one-time gate.
What is the fastest way to get started? Pick an open-source tool you can run in minutes (Langfuse or Arize Phoenix are common first choices), add tracing to your app, assemble a small dataset of real inputs, and wire up a basic LLM-as-judge. You can have meaningful visibility and a first eval running in an afternoon, then expand from there.
Final thoughts
You cannot improve what you cannot measure, and with LLMs you cannot even trust what you cannot see. Evaluation and observability turn a non-deterministic black box into a system you can debug, improve, and operate with confidence. For most teams the fastest start is an open-source all-rounder like Langfuse or Arize Phoenix, paired with an evaluation discipline - real datasets, a calibrated judge, evals in CI, and continuous production monitoring. Match the tool to how you build, measure across quality, cost, latency, and safety, and treat the whole thing as a loop rather than a launch checklist. Start small - one tool, a modest dataset, and tracing switched on - and let the loop compound over time; the teams that measure early and consistently are the ones whose AI keeps getting better, while the ones that skip it ship a demo that quietly degrades in production.
If you want a partner to build, evaluate, and operate production-grade AI - with the measurement and monitoring that keep it reliable - VOCSO can help, from AI development to dedicated machine-learning engineers who make quality measurable from day one.
Keep reading
An in-depth 2026 guide to the best AI chatbot platforms for websites - how they work, how to choose one, a detailed comparison of the top…
An AI agent is software that uses a language model to plan steps toward a goal and act through tools. Here is what agents are made…
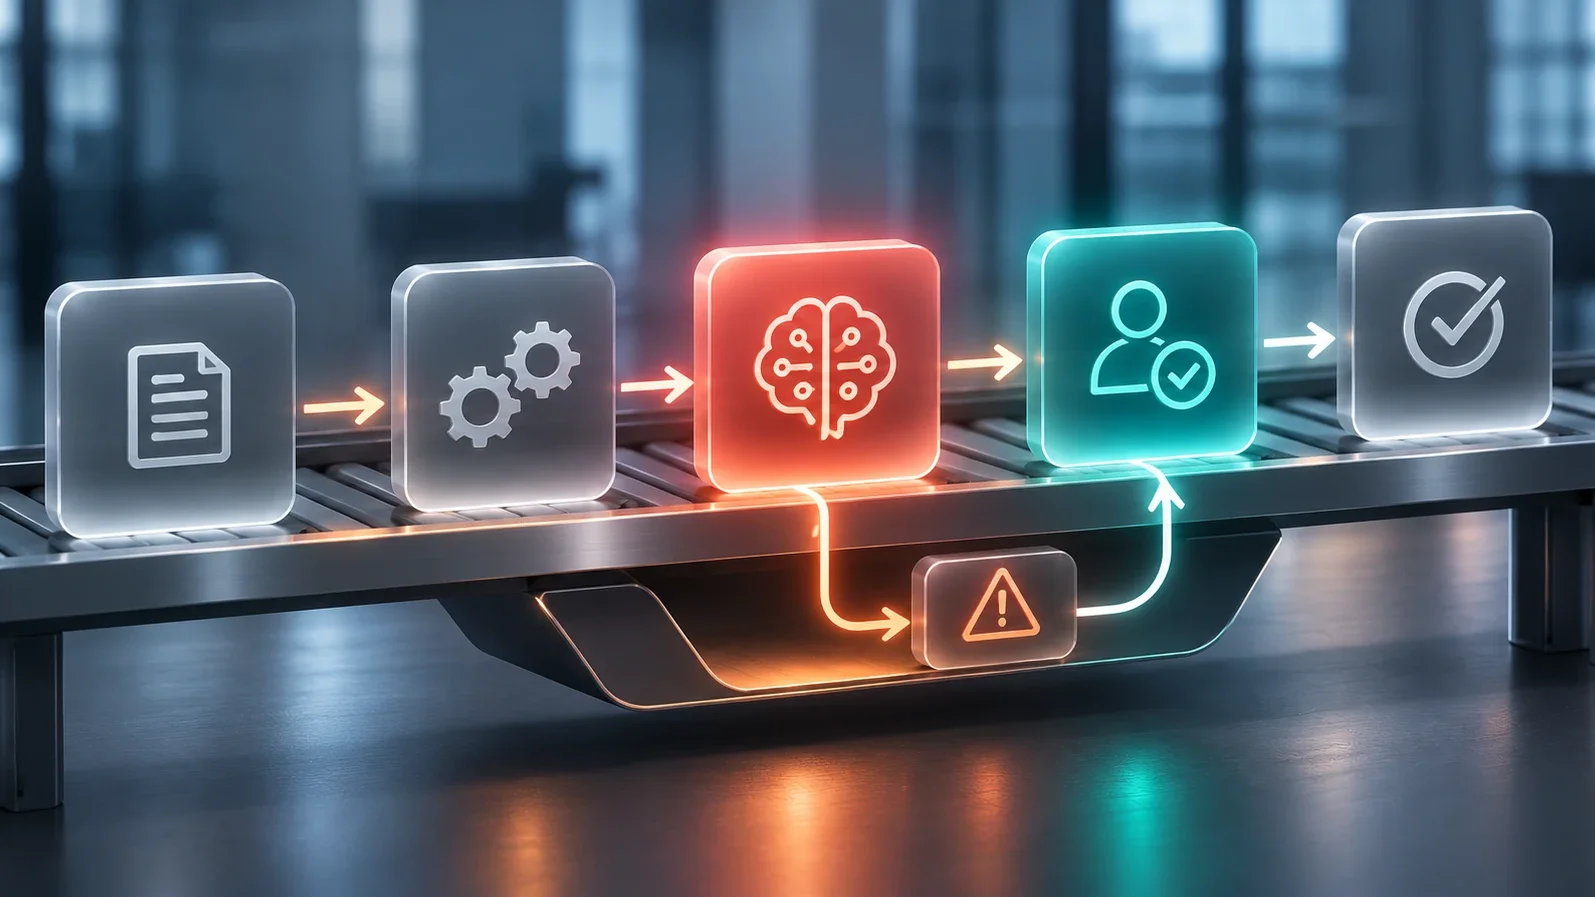
An agentic workflow lets an AI model decide some steps of a business process while rules handle the rest. How it differs from Zapier, n8n and…